Private doesn't mean out of reach.
Run models on hardware you own and use them from chat, VS Code, MCP or an OpenAI-compatible API. No token limits, and no network configuration.
Not ready yet? See how it works
Install, pick, use it anywhere.
Install the agent
One command on each machine you want to reach. It sets up the service and the engines, and pairs the machine to your account.
$ curl -fsSL https://qadenza.ai/install.sh | sh PS> irm https://qadenza.ai/install.ps1 | iexPick a model that fits
Every model is checked against the memory that's free right now, before you download it.
Use it from anywhere
The relay reaches your machine from any network. Use it wherever you already work.
- Phone
- VS Code
- Claude Code
- Cursor
- MCP
- OpenAI API
Feels like a cloud app. Runs on your machine.
Everything you'd expect from a hosted assistant, without handing your data to one.
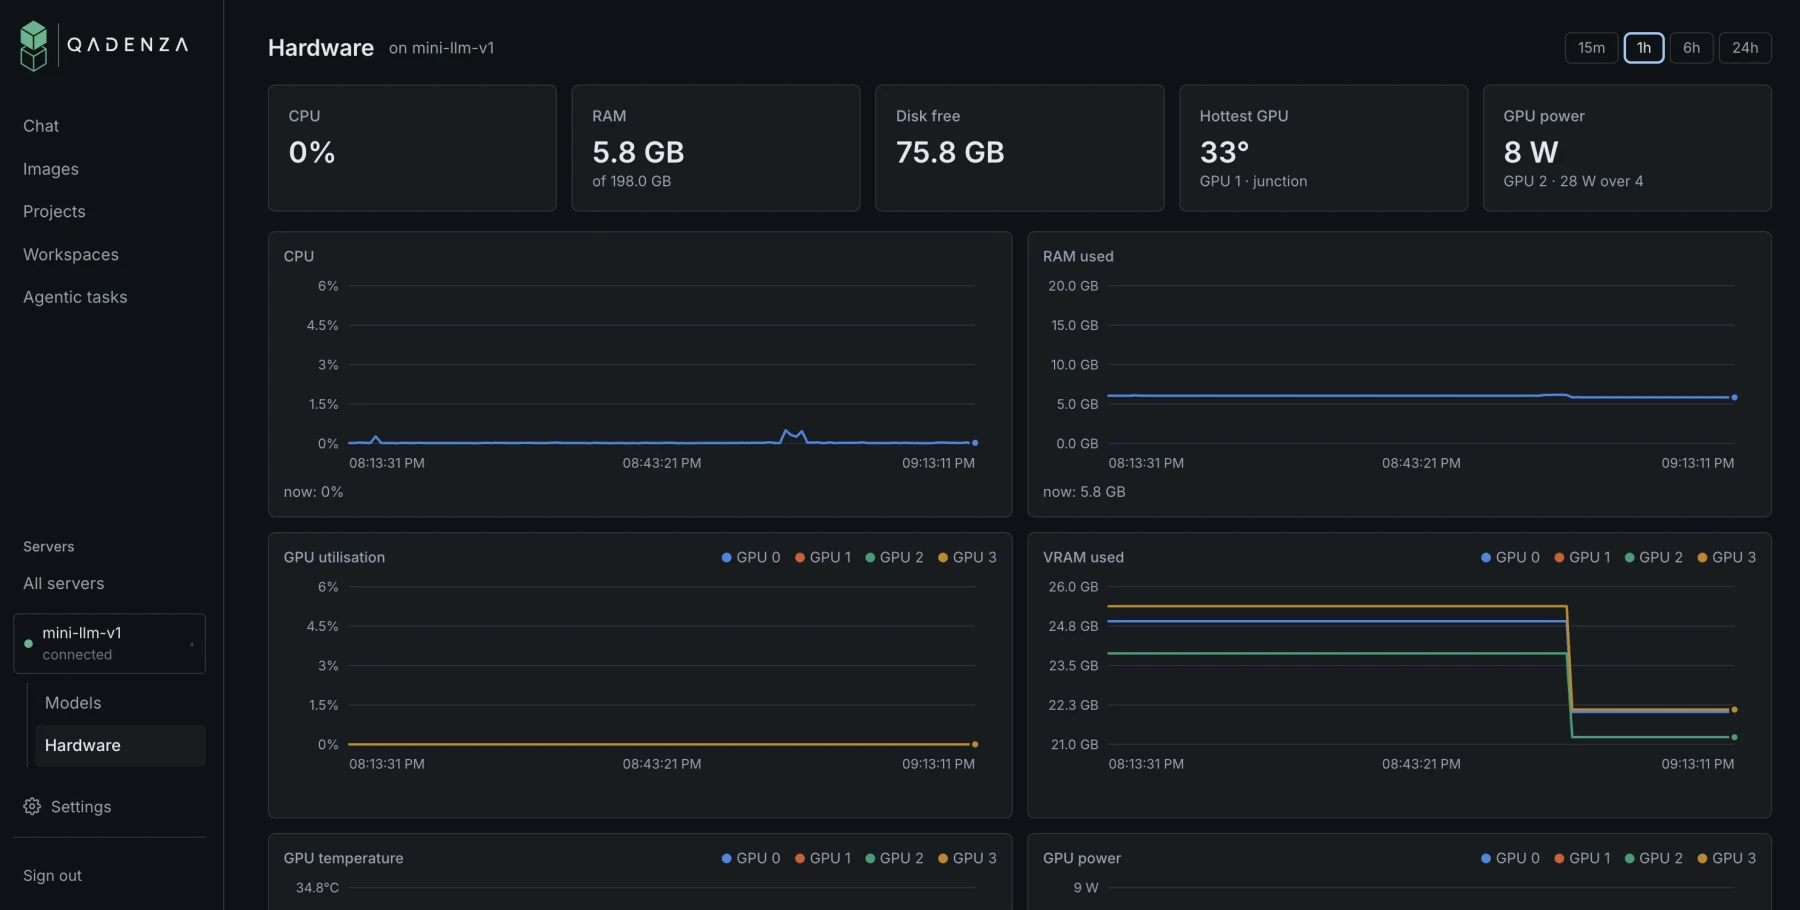
Every machine, one dashboard.
CPU, RAM, GPU temperature and power with an hour of history. Load, unload and pull models from wherever you are.
Flexible models, no token limits.
Ollama or llama.cpp, with a model split across every card in the box. One heavy coding-agent month on a hosted API is a recurring bill. The same workload on your own card costs the electricity.
Models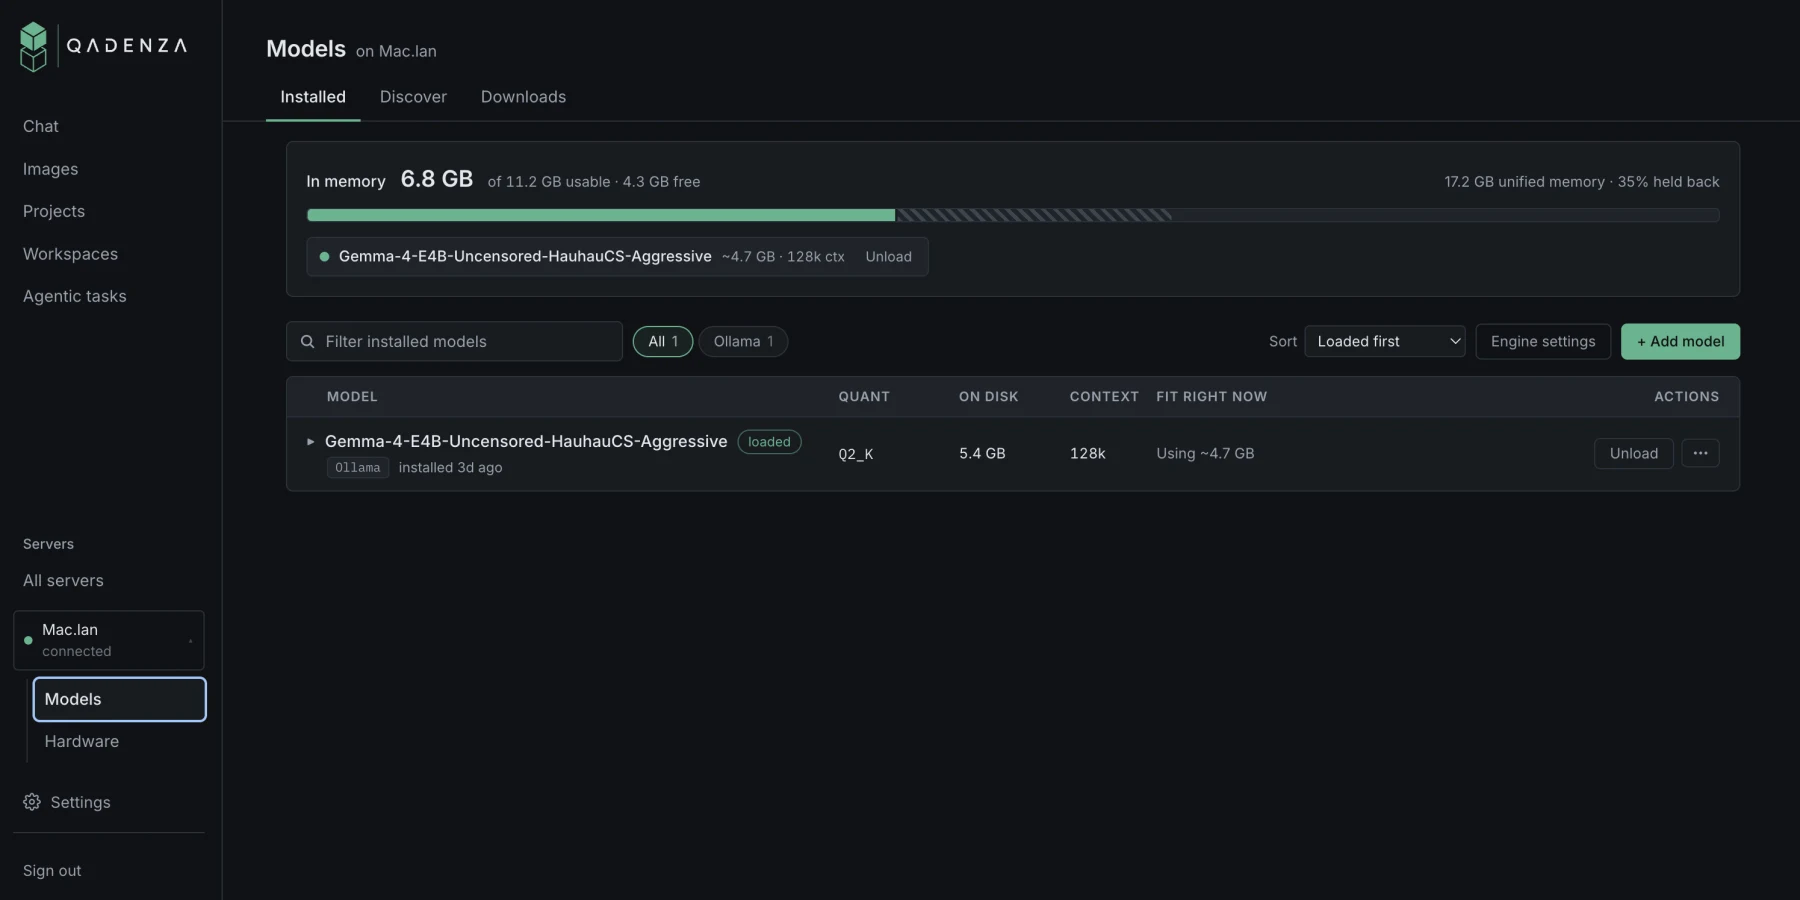
Your models inside VS Code, Claude Code and Cursor.
The extension turns your models into a coding agent that reads your project and proposes edits. Use models from any of your machines.
The extension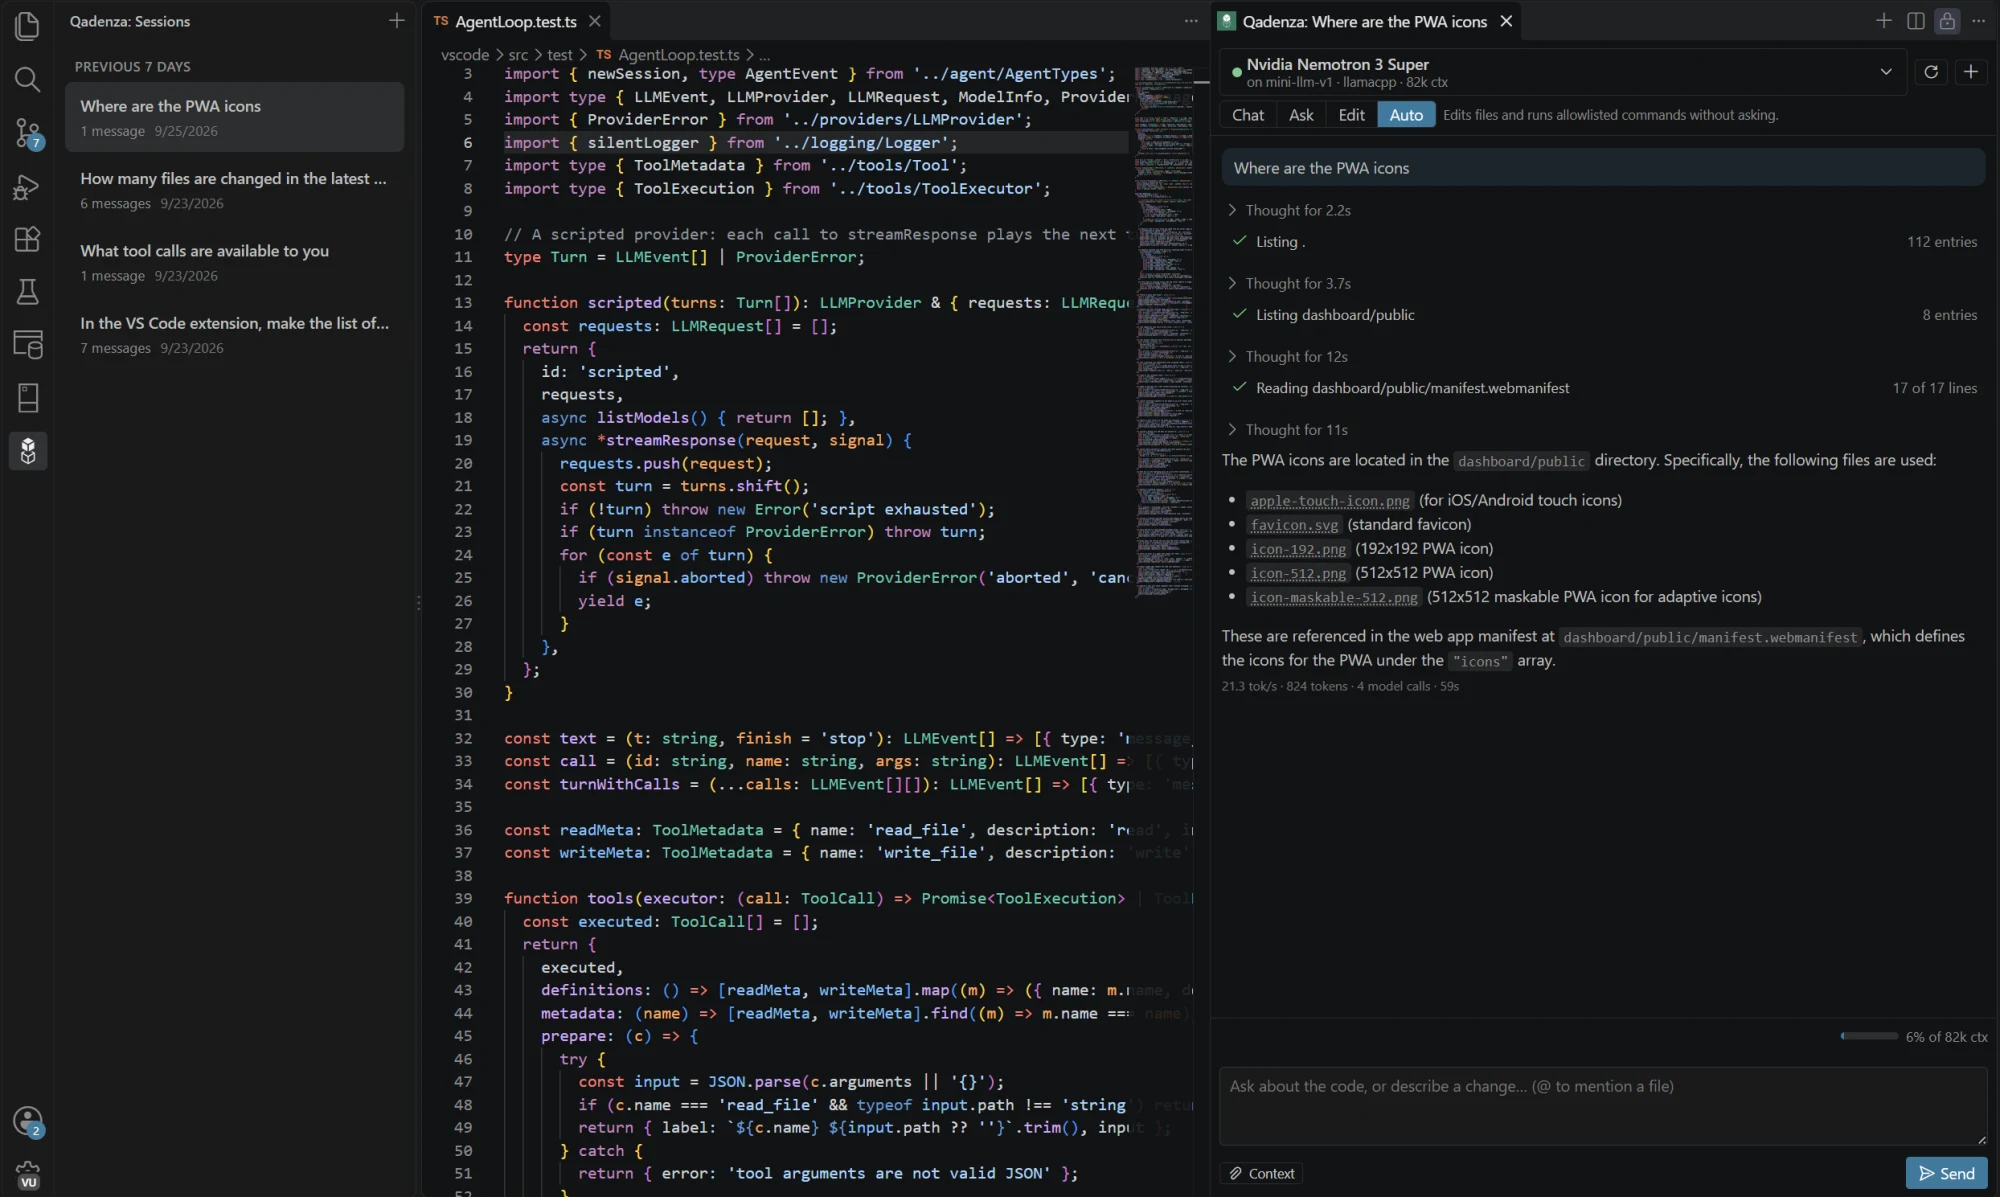
MCP, both ways.
Give your models tools like Filesystem, Git and GitHub, or add Qadenza to Claude Code and other agents.
Integrationstools: server_status · list_models · chat
An OpenAI-compatible API.
The official SDKs, Cursor, Continue, Open WebUI and curl work unchanged. Tokens can be revoked any time.
The APIbase_url="https://<your relay>/v1",
api_key="<token>")
What passes through our servers, and what doesn't.
Reaching your machine from anywhere means your traffic crosses the Qadenza relay. Here is exactly what that involves.
- IN TRANSITYour requests and the model's replies, between your browser or tools and your machine. Encrypted on the way.
- STOREDNone of it. We never store prompts, replies or files. We keep your account, the list of machines you've paired, and standard server logs.
- TELEMETRYOn by default: daily speed figures per model, like tokens per second and peak GPU temperature. Never prompts, replies, files or model names. One switch in Organization settings turns it off.
- OPEN PORTSNone. Your machine dials out to the relay; nothing on it listens to the internet.
Everything the agent connects to
Outbound only. Check it against your firewall logs.
- relay.qadenza.ai
- The encrypted tunnel that lets you reach this machine.
- api.qadenza.ai
- Sign-in, pairing, agent updates, and telemetry if it's on.
- huggingface.co · modelscope.cn · civitai.com · registry.ollama.ai
- Only when you download a model.
- github.com
- Only when installing or updating an engine or runtime, such as llama.cpp.
No internet? No problem.
For teams that can't let data leave the building, we deploy the whole stack inside your network: agents, dashboard and relay. The full stack runs with zero outbound connections, so the list of hosts above is empty.
- Runs on isolated networks with no outbound connection
- Models and updates delivered offline, on your schedule
- Same chat, model manager and VS Code extension as online
- Your hardware, your network, your data. Nothing leaves.
Questions people ask first.
Why not just run Ollama + Tailscale?
For one machine and one laptop, that works, and Ollama still runs underneath Qadenza if you use it. Qadenza is the part you'd otherwise build yourself on top:
- No VPN client on every device. The relay is plain HTTPS, so a browser, a phone, or any OpenAI client reaches your models.
- Every machine in one dashboard. GPU temps, VRAM and power, and loading or pulling models, without SSH.
- Fit, before you download. Each model is checked against the memory that's free right now.
- llama.cpp next to Ollama, with a model split across every GPU in the box.
- A coding agent in VS Code, MCP both ways, and API tokens you can revoke.
Do my prompts go through your servers?
When you reach a machine remotely, yes, in transit and encrypted. We don't store them or use them for anything. Air-gapped, they never touch us. What the relay sees.
What hardware do I need?
Any Mac, Linux or Windows machine you can install the agent on. Qadenza tells you which models fit its memory before you download one. More VRAM means bigger models; CPU-only machines run small ones.
Your GPU, from anywhere.
Qadenza is in closed beta. Leave your email and we'll send an invite when a spot opens.